For the past three years, every model we have integrated into our clients’ projects has shared the same reflex: it writes. We ask a question, it responds with text, and we then spend a considerable amount of time turning that text into something our code can use: parsing imperfect JSON, validating schemas, and retrying when the model decides to add an introductory sentence before its opening brace.
On September 16, 2026, TypeSafe AI opened early access to Jev, a model that approaches the problem from the other end. Jev does not write. It cannot explain its reasoning. It receives a state and typed questions, then returns structured decisions with calibrated probabilities in 70 to 500 milliseconds. The company calls this a new category: System One models.
For an agency like ours, building websites and business applications where every LLM call costs time and money, this shift deserves a closer look. Here is what this AI decision model actually does, how to interpret the published figures, and how to integrate it into an existing application.
Jev explained in under a minute
This video gives a simple explanation of the difference between an LLM that generates text and Jev, which returns a structured decision.
A model that generates no text: the System One approach
The name comes directly from Daniel Kahneman’s System 1 / System 2. System 1 is immediate, intuitive judgement: recognising a face or spotting an anomaly without deliberation. System 2 is slow, sequential, expensive reasoning.
TypeSafe’s argument fits into one sentence: today’s large language models all try to be System 2. They reason out loud, one token at a time, even when answering questions that require no deliberation. Assigning an incoming ticket to one of four categories does not need an eight-hundred-token chain of thought.
What TypeSafe calls RLCD
Where conventional LLMs are trained on human preferences through the familiar RLHF approach, Jev relies on what the company calls Reinforcement Learning for Calibrated Decisions (RLCD). The training objective is no longer to produce an answer that pleases a human evaluator, but to produce a decision whose stated probability is honest.
This distinction matters and is often misunderstood. A well-calibrated model reporting 70% confidence should be wrong 30% of the time. No more, no less. That is precisely what general-purpose LLMs lack: their overconfidence is documented, and they state what they know and what they invent with the same assurance.
Behind Jev is Diogo Almeida, a former OpenAI researcher who contributed to ChatGPT. That background helps explain some of the attention surrounding the launch.
Why having no output tokens changes everything
Jev has no autoregressive loop. You send a state, which can be a string, a JSON object or an array, together with a set of typed questions. The model evaluates all of them in parallel against that same state, in a single call.
There are three direct consequences:
- Latency drops sharply, because there is no sequential generation to wait for.
- Type errors become structurally impossible: the response cannot fall outside the schema you defined. TypeSafe claims a 0% hallucination rate, but we need to be clear about what that means. We return to this below.
- Output costs disappear. TypeSafe charges for input tokens and says output is free, “too cheap to meter”.
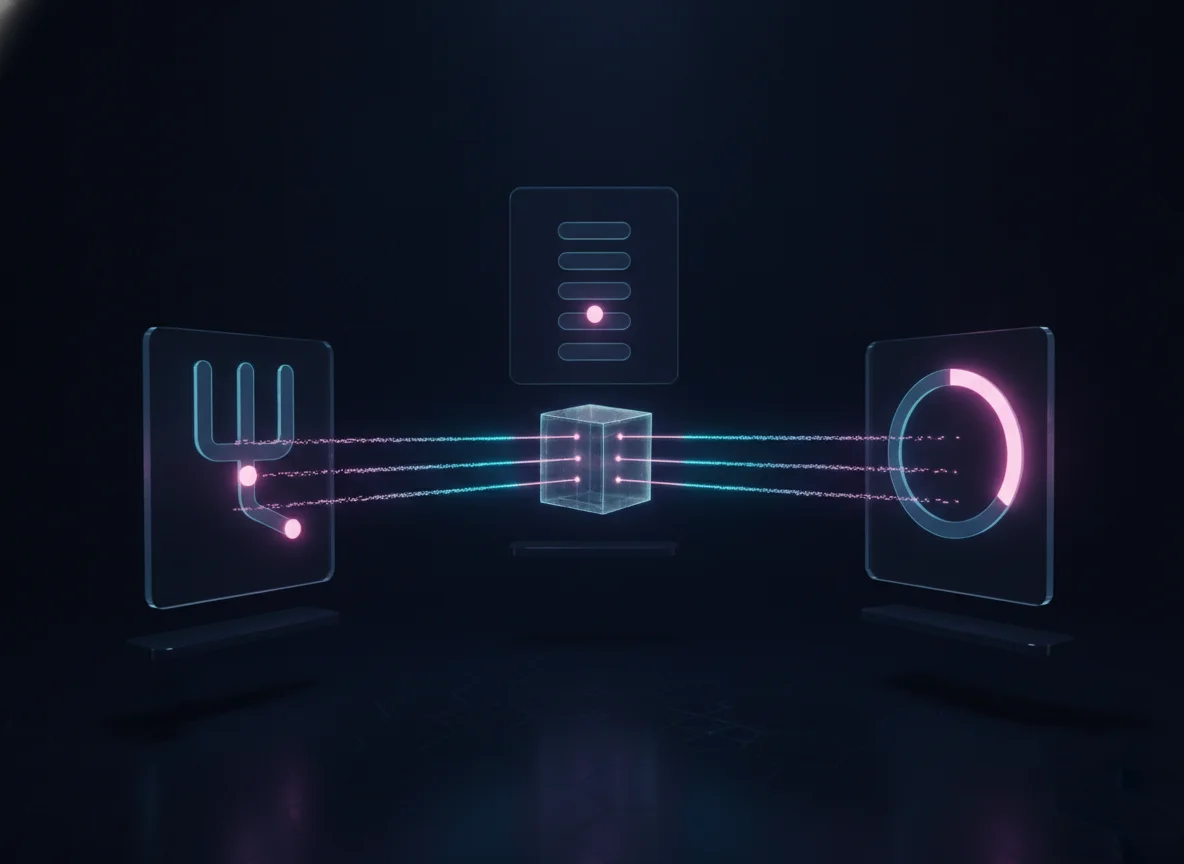
Choice, Score, Noul: three primitives, one request
The API deliberately limits itself to three question types. That simplicity makes the model usable in production without fifty pages of documentation.
Choice — selecting from a closed list
You provide options, and the model selects one and returns the probability distribution across all of them, along with a confidence value. This is the primitive for routing and classification: which department should handle a ticket, which category an article belongs to, or which model to call next. It supports up to 255 options.
Score — rating against a defined scale
You describe ordered levels, such as “cosmetic”, “disruptive but with a workaround” and “blocking”. The model places the state on that scale, including fractional values. This is the primitive for rubric-based evaluation: incident severity, product listing quality or a customer’s level of frustration.
Noul — a Boolean probability
One statement, and a probability between 0 and 1 that it is true. “Does this message express urgency?” or “Does this order present a fraud risk?” It is not a plain Boolean: it is a number against which you set your own thresholds.
The philosophy set out in the documentation deserves attention because it goes against common LLM usage: break complex reasoning into separate atomic questions, then combine the results using logic in your code. In other words, you ask the model for basic judgements that your code orchestrates, rather than asking it to do your thinking for you.
Here is what a call looks like using the proposed integration with Vercel’s AI SDK:
import { experimental_evaluate } from 'ai';
import { typeSafeAi } from '@ai-sdk/typesafe-ai';

const result = await experimental_evaluate({
  model: typeSafeAi.evaluationModel('jev-latest'),
  state: {
    message: 'I was charged twice. Please refund the duplicate.',
  },
  questions: {
    department: {
      type: 'choice',
      instructions: 'Which team should handle this?',
      criteria: {
        billing: 'Charges, invoices, and refunds',
        technical: 'Bugs, outages, and integrations',
        other: 'Anything else',
      },
    },
    severity: {
      type: 'score',
      instructions: 'How severe is this issue?',
      criteria: [
        'Cosmetic; functionality works',
        'Functionality impaired; workaround exists',
        'Blocking; no workaround',
      ],
    },
    requestsRefund: {
      type: 'boolean',
      instructions: 'Is the customer requesting a refund?',
      criteria: {
        true: 'Explicitly requests money back',
        false: 'Does not request money back',
      },
    },
  },
});

result.answers.department.choice;        // 'billing' | 'technical' | 'other'
result.answers.department.probabilities; // full distribution
result.answers.severity.score;           // number in [0, 2]
result.answers.requestsRefund.probability; // P(true) in [0, 1]
Three different kinds of question, one network round trip. Note that Vercel chose the neutral name boolean for the primitive TypeSafe calls Noul.
Latency and cost: the published figures and what they mean
TypeSafe’s published figures are striking. They deserve to be quoted with their caveats, something the surrounding enthusiasm rarely allows for.
| Metric | Reported value |
|---|---|
| End-to-end response time | 70–500 ms |
| Input token price | $0.042 per million ($42 per billion) |
| Output token price | Free |
| Claimed speed improvement | 40×–200× depending on the task |
| Maximum options in a Choice | 255 options |
In the workflow evaluations published by the vendor, Jev reaches 76.0% accuracy at roughly $0.0001 per call and 0.4 seconds, compared with 76.1% for GPT-5.6 Luna at $0.0025 and 14.5 seconds, and 78.4% for Claude Opus 5 at $0.4856 and 92.1 seconds.
Four caveats matter here:
- The TypeSafe team designed these workflows. An in-house benchmark primarily measures what its author chose to measure. The multipliers displayed on the homepage, 193.6× faster and 444.6× cheaper, represent the upper end of the range by the vendor’s own admission.
- The price may be subsidised, as TypeSafe acknowledges. Building a cost structure around an early-access price would be unwise.
- The 0% hallucination figure is not an empirical result, but a schema guarantee. The model cannot answer outside the supplied options. It can still choose the wrong option: the guarantee covers format, never correctness.
- On complex tasks, a large model still leads. Jev explicitly does not aim to be a general-purpose model. For writing, summarisation or multi-step reasoning, it is simply not a candidate.
Five practical use cases for a website or business application
This is where the subject becomes interesting for our projects. Here is where an AI decision model can deliver an immediate benefit, ordered by ease of implementation.
- Comment and review moderation. Two Noul questions, toxicity and spam, for each submission, with thresholds deciding whether to publish, hold for review or reject. At 0.4 seconds, this fits within the request cycle.
- Form and lead qualification. A Choice to route the enquiry to the right person, a Score to assess how well-developed the need is, and a Noul to detect requests outside your scope. The contact form stops being a black box that someone empties on Monday morning.
- Support triage. Priority, responsible department and the presence of a contractual deadline: three questions, one call, and a ticket that arrives in your tool already labelled.
- E-commerce checks. A risk score at checkout, detection of inconsistencies between shipping and billing addresses, and preliminary assessment of refund requests.
- Agent guardrails. This is the most underestimated use case. If you run AI agents in production, each safety check currently assigned to an expensive sub-agent could become a 0.4-second call. The same applies to model routing: let Jev decide which larger model to call next.
The decision criterion is simple. For every LLM call in your system, ask: am I actually using the generated text, or am I only extracting a value from it? In the second case, you are paying for System 2 to do a System 1 job.
Integrating a decision model into an existing application
The API is deliberately minimal: one endpoint, one state, one set of questions. You do not need an SDK to get started. A single HTTP call works from any language.
curl -X POST https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "jev-latest",
    "state": "I have been trying to connect my Stripe account for 3 days without success. I am losing sales.",
    "questions": {
      "urgency": {
        "type": "noul",
        "instructions": "Does this message express urgency?"
      },
      "department": {
        "type": "choice",
        "instructions": "Which department should handle this request?",
        "criteria": {
          "billing": "Payments, invoices, refunds",
          "technical": "Bugs, outages, integrations",
          "other": "Everything else"
        }
      }
    }
  }'
One request, two different kinds of question, and a typed response your code can use directly.
Four architecture decisions to make before going live:
- Synchronous or asynchronous. At 400 milliseconds, a call fits within an HTTP request cycle without degrading the experience. As soon as you chain several decisions or process a batch, use a queue: median latency tells you nothing about the 99th percentile.
- Decide failure behaviour in advance. For moderation, block and hold for human review. For order scoring, let the order through and flag it, otherwise sales will stop the day the API goes down. This is a business decision, not a technical one: make it with the people responsible for the process.
- Keep thresholds configurable. Decision thresholds such as 0.5 or 0.9 have no reason to be hardcoded. They will change after the first few weeks of observation, and you will want to adjust them without redeploying.
- Keep the API key in the environment. Never in a version-controlled file or a configuration table exposed to the client.
Using an SDK to remain provider-neutral
If you prefer not to write the HTTP call yourself, Jev is available through Vercel AI Gateway under the identifier typesafe-ai/jev. A proposed integration with Vercel’s AI SDK, in the form of an experimental_evaluate() function, has been open since September 16, 2026. That is the API shown above. Its main value is provider neutrality, rather than typing convenience: when a competitor releases its own decision model, the calling code stays the same.
In either case, isolate the call behind your own interface. Put an evaluate(state, questions) function in your code, and the rest of the application never needs to know who makes the decision.
Mistakes to avoid
We have seen enough poorly scoped AI projects to anticipate the pitfalls.
- Not measuring calibration on your own data. A model calibrated on its vendor’s benchmarks is not necessarily calibrated on your tickets, in your industry or in French. Build a set of one hundred manually labelled cases and check that the confidence thresholds hold up. Half a day of work can save you six months of silently incorrect automation.
- Confusing confidence with correctness. A probability of 0.92 is not a guarantee. It means that, out of one hundred similar cases, eight should be wrong. Your logic needs to account for those eight.
- Forgetting GDPR. Sending the contents of a comment, form or order to a third-party API is a transfer of personal data. Record the processing activity, mention the processor in your privacy policy, and pay attention to server locations. Address this at the start of the project, not at launch.
- Building a dependency with no way out. The service is in early access, the pricing is new, and the company is only a few months old. Isolate the call behind your own interface and keep a fallback implementation, even if it is just a simple set of rules.
- Using it for things it cannot do. Jev does not write, summarise or explain its choices. If your needs include generation, you need both: a decision model to decide and a language model to produce content.
What to take away
Jev’s appeal is not its raw performance: on accuracy alone, large models remain slightly ahead. It is the relationship between the cost of a decision and its value. When a classification drops from 2.5 cents and fourteen seconds to one hundredth of a cent and four tenths of a second, the possibilities change. Features that nobody would have considered because they made no economic sense become viable.
Our recommendation at this stage: do not rewrite anything. Identify the two or three most expensive decision flows in your existing applications, whether measured in money, latency or human processing time, and test them on a real sample. Within a day, you will know whether the benefit is there.
Wondering which flows in your website or business application could benefit from this kind of model? That is exactly the kind of assessment we carry out at Partikuls. Let’s talk: an hour is usually enough to identify the two or three obvious candidates and rule out the misleading ones.
Sources
- Introducing System One Models & Jev — TypeSafe AI Blog
- TypeSafe AI Documentation — Introduction
- Jev API, Pricing & Playground — Vercel AI Gateway
- Issue #20846 —
experimental_evaluatewith a TypeSafe provider, vercel/ai repository - TypeSafe Jev: the First Decision-Only Model Class, Benchmarked and Priced — Developers Digest